site logo
projects resume gmail linkedin github

hi i'm

jayadithya

AI / ML engineer

i build ai systems bottom-up, from tokenizers and pipelines to inference and eval.

chennai, tamil nadu, india.

view résumé
jayadithya

the t-shaped engineer

broad across the bar. deep down the stem.

frontend ui/ux backend scraping devops
ai / llm systems

Frontend venuma?
Frontend iruku.

view projects >

Backend venuma?
Backend iruku.

view projects >

ui/ux venuma?
ui/ux iruku.

view projects >

ai venuma?
ai iruku.

view projects >

Projects

every project below answers three questions: what problem it solves, what i gave up to solve it, how it works.
tamil tokenizer

ai backend
problem
general-purpose subword vocabularies shatter tamil into far too many pieces, so tamil corpora cost more tokens and train slower than english ones.
tradeoff
hand-writing bpe in rust instead of building on sentencepiece or huggingface tokenizers. that bought the speed and cost me the ready-made training loop.
solution
247 tamil character clusters as base tokens, aho-corasick multi-pattern encoding, rayon-parallel bpe training. 11-16x faster than sentencepiece, 32k vocab on huggingface, 23 tests on every merge.

sivabharani comments

ai backend
problem
the channel answers subscriber questions inside 2,000+ youtube videos. nobody could search their own name to find the one video where he answered them.
tradeoff
an llm pass over every transcript chunk instead of search alone. that narrows the index and costs a full run over 1.18m chunks, and youtube's english auto-transcripts were too broken to trust, so the model had to carry the work.
solution
2,755 videos scraped, 1,185,665 chunks run through local gemma 4-bit inference to keep only the ones naming a person. search a name, get the video and the timestamp. dataset on huggingface.

resume agent skill

ai
problem
rewriting the same resume for every job, then fighting word processors to ship a docx and a pdf that parse cleanly.
tradeoff
generation over hand-editing. formatting stays consistent across applications, and every resume reads like the same person wrote it.
solution
an agent skill that reads a job description, writes the tailored content, exports docx and pdf, and logs the application so nothing goes out untracked. this site's resume came out of it.

java vulnerability checker

ai backend
problem
static analyzers miss sql injection, xss and insecure deserialization, and general code models had no idea what a vulnerable java pattern looks like.
tradeoff
budget on dedup instead of parameters. the 7b beat my 14b run, 80.39% against 78.43% on the same 102 cases, which says the merged corpora were dirtier than they needed to be.
solution
seven pipeline stages from raw jsonl to conversation-formatted sft, sha256 dedup on normalized lines, lora fine-tune, then a fixed 102-case eval any checkpoint runs through one function call. weights on huggingface.

kaggle automation

backend ai
problem
kaggle sessions expire after 12 hours, so a training run that outlasts one is gone, and watching that by hand means babysitting a browser tab.
tradeoff
pooling nineteen accounts and sharding one job across them instead of waiting out a single session. 223 runs' worth of gpu hours, paid for in credential handling and retry logic.
solution
a dockerized fastapi control plane on ec2 that pools api keys, shards jobs across accounts, and alerts on the 12-hour cutoff. github actions runs uv sync, ruff and pytest over 12 test suites.
FitCheck logo

fitcheck

frontend ai ui/ux
problem
fashionclip runs in the browser but it can't reason about an outfit, only match an image to a garment. a shopping site needs the reasoning and can't afford a server-side model doing it.
tradeoff
distilling two teachers into a student that still runs client-side. the student keeps 91.6% of the teacher's judged recommendation quality on a 1,000-image bench, generates 39% more tokens per second on 3.14x less vram, and reasoning that came free from the 120b teacher now comes from a 2.9k-example tuning run.
solution
qwen3-vl-8b labeled 106k fashion photos, which became 538k caption-and-qa pairs for perception tuning, then gpt-oss-120b wrote 2,923 outfit recommendations with color and silhouette rationales for reasoning tuning. evaluated two ways: a 1,000-image bench and a blind human study over 297 ratings. first-author ieee paper, model and three datasets on huggingface.

where i've been

ai research intern

07/2025 - 10/2025

blubridge technologies · chennai

  • built operator-fusion passes in mlir, cutting kernel launch overhead ~20%.
  • lowered dialect ops to llvm ir with shape inference for dynamic tensors.
  • hardened passes with 40+ lit tests wired into ci.

b.tech, artificial intelligence and data science

2026

dr. m.g.r. educational and research institute · chennai · 8.0/10

first author, ieee tqcebt 2026

2026

"FitCheck: A Multi-Modular AI Framework for Cross-Cultural Fashion Recommendation via Black-Box Data Distillation" · pune, india

read the paper (pdf) · doi 10.1109/tqcebt67648.2026.11681836

where i commit

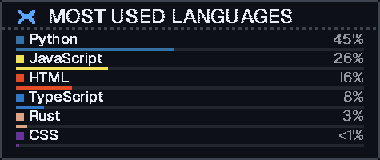
stats, languages and streak — pixel cards redrawn straight from the github api every day.
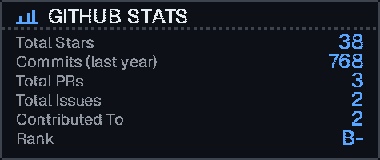
GitHub stats for barryallen16: stars earned, commits this year, pull requests, issues and repositories contributed to Most used languages on GitHub for barryallen16, listed with percentages Contribution streak for barryallen16: total contributions, current streak and longest streak